Reasoning and Evaluation
Overview
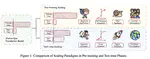
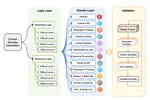
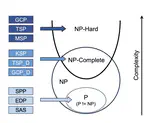
Most reasoning benchmarks emphasize deduction, where the rules are given and the task is to apply them. Organizing tasks by complexity class instead gives a principled difficulty axis and a way to say precisely what a model can and cannot do, and refreshing the instances regularly keeps the benchmark from being absorbed into the next round of training data. Induction, where the rule itself has to be inferred from observations, is the more demanding direction and the one closer to scientific discovery, and current models struggle with even its simplest classes. Alongside benchmark construction, this line covers how context shapes apparent reasoning ability, how reasoning behaves under test-time scaling, and how to find the slices of data where a system quietly fails.
Publications